> For the complete documentation index, see [llms.txt](https://docs.concurrence.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.concurrence.com/agent/reasoning-engine.md).
# Reasoning Engine
How agent guidance, Context Graphs, tools, and channel controls coordinate reasoning, ongoing work, and responses across supported interactions.
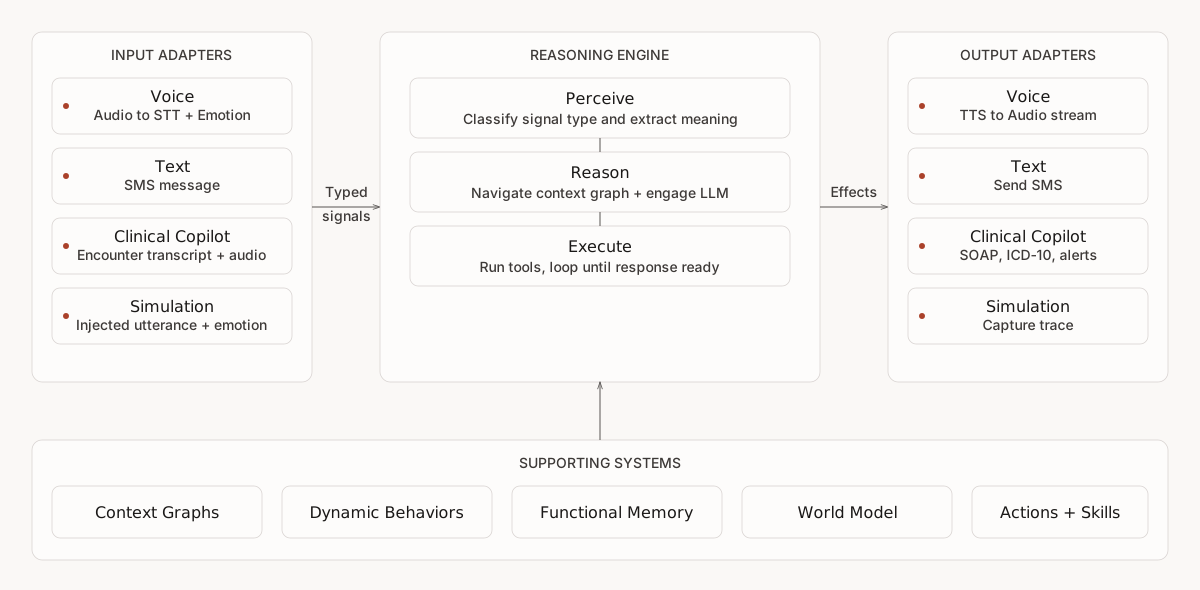
The reasoning engine combines an agent's guidance, a Context Graph's problem definition, and available evidence to decide what to do next. Supported state-machine paths can navigate a workflow, invoke tools, use their results, and continue without requiring another user message. Voice, text, and simulation reuse definitions and selected reasoning components, while their execution, delivery, and connection lifecycles differ.
## Why a Unified Engine Matters
For the broader architecture, read [Universal Reasoning and the Liquid World Model](/agent/universal-reasoning.md). It explains why a reasoning system combines software-defined problems, exact computation, fast decisions, and model deliberation over source-linked views, and distinguishes that design from the execution contracts on this page.
A workflow's objective can stay the same across channels even when its interaction changes. An availability lookup may support a spoken conversation or an asynchronous message. The agent still needs to interpret the request, use the permitted tools, and explain their result, while each channel handles waiting, interruption, and delivery differently.
Concurrence separates reusable agent and problem definitions from those channel concerns. Teams can change workflow guidance without rebuilding audio transport, or add a supported channel while retaining the same authored objectives. Each channel still needs its own validation.
## What the Designer Controls
Agent and Context Graph definitions are declarative assets: they describe the intended behavior and can be versioned, reviewed, and evaluated together.
| Part | Designer specifies | Role during execution |
| -------------------------------- | -------------------------------------------------------------------------- | ----------------------------------------------------------------------- |
| **Agent** | Role, communication style, and general guidance | Gives the model a consistent perspective for interpreting the task |
| **Context Graph** | Objectives, states, transitions, and state-specific instructions | Defines the problem and the paths available for addressing it |
| **Tool binding** | Eligible operations, execution timing, result delivery, and retention | Connects a state's work to the tools and result-handling rules it needs |
| **Service and runtime controls** | Channel settings, authorization, validation, and supported safety behavior | Apply the operating boundaries for that deployment |
Use model judgment where interpretation is useful, such as understanding a request or explaining available options. Put requirements that must block an operation into the corresponding authorization, validation, or supported approval boundary. A state instruction to obtain confirmation guides the agent; an enforced confirmation requirement also needs a tool or approval check that rejects execution without it.
This lets a workflow vary how much judgment each step allows. It does not make model-backed navigation or responses deterministic. See [Context Graphs](/agent/context-graphs.md) and [Runtime Safety](/operations-and-safety/runtime-safety.md) for the specific controls.
## Cut, Navigate, Engage
Concurrence uses three operations to coordinate the voice timeline and signal-driven text flow:
1. **Cut** - Decide whether an incoming signal creates a boundary in the current interaction phase.
2. **Navigate** - Select the next context-graph state or channel-level unit of work from the current session state.
3. **Engage** - Carry out that selection by generating a response, executing tools, scheduling a deadline, or delivering channel output.
The operations appear at more than one layer:
| Scale | Cut | Navigate | Engage |
| ------------------ | -------------------------------------------------- | ------------------------------------------------------------ | -------------------------------------------- |
| **Conversation** | A user turn or qualifying event prompts evaluation | Select a path through the context graph | Generate a response and execute tools |
| **Voice timeline** | A timing or session signal creates a boundary | Select breath, filler, hold, response, or listening behavior | Schedule or play the selected audio behavior |
| **Text flow** | A queued message or event becomes the next item | Run the shared reasoning path | Deliver or persist the resulting effects |
This coordination keeps fillers, silence handling, empathy pauses, tool progress narration, and barge-in recovery on one voice timeline. The [voice timeline](/channels/voice/audio-pipeline.md#voice-timeline) describes how it operates within each turn.
The [Universal Reasoning Harness design direction](#design-direction-universal-reasoning-harness) extends this coordination to longer-running and non-conversational work. Its broader context and scheduling contract is distinct from the current channel-specific operations described here.
## Signals and Effects
The engine communicates through two primitives.
**Signals** represent something that happened. On signal-processing paths, adapters normalize relevant input into typed signals:
| Signal | What It Represents |
| ------------------ | ----------------------------------------------------------------------------- |
| **Utterance** | The caller or user said something (text, from any source) |
| **Emotion** | An emotional state update from acoustic or transcript analysis when enabled |
| **Tool result** | A tool execution completed with a result |
| **Silence** | The caller has been silent beyond the configured threshold |
| **Barge-in** | The caller interrupted the agent mid-speech |
| **External event** | An injected event from an operator, surface submission, or external system |
| **System** | A system-level event such as a timeout, connection change, or error condition |
**Effects** are typed outputs in the shared reasoning contract. Some request future delivery; others report work already performed. For example, a tool-called effect can report a tool invocation that the reasoning path has already executed, rather than ask a downstream scheduler to execute it again. The specific type and runtime determine the lifecycle. The table maps output concepts to channel behavior; it does not imply one identical effect-consumption loop or prove external completion:
| Effect | Voice | SMS | Simulation |
| ---------------------- | -------------------------------------------------------- | ------------------------------------------------------------------------- | -------------------------------------------------- |
| **Respond** | Stream the generated response through the voice pipeline | Send as an SMS message | Capture as simulation output |
| **Filler** | Play filler audio ("Let me check on that...") | No-op | No-op |
| **Pause** | Hold deliberate silence | No caller-facing output | Capture the effect when applicable |
| **Tool call / result** | Execute through the voice tool path; process its result | Supported execution path may report the completed invocation as an effect | Same real tool path, with simulation-tagged writes |
| **Terminate** | Hang up after final speech | End session | Return final state |
| **Transition** | Records a state change; no caller-facing output | Same | Capture in trace log |
| **Observe** | Emits an analytics event; no caller-facing output | Same | Capture in trace log |
## The Pipeline
The interaction can be understood through three stages. A signal can update context or control the channel without requiring a new model response; for example, an emotion update can inform later speech, while barge-in can interrupt playback.
**Perceive.** On native signal-processing paths, the modality adapter converts relevant input into typed signals. The native voice path produces utterance signals from speech-to-text and emotion signals when prosody analysis is enabled. An SMS adapter produces utterance signals from message text. A simulation adapter injects both from test parameters.
**Reason.** The native state-machine path implements cut/navigate/engage at the conversation level:
1. **Navigate** - The context graph engine determines the current state, evaluates transition conditions, and selects the appropriate action.
2. **Engage** - The response generation model produces a reply, drawing on the agent's persona, current state guidance, selected memory, patient data from the world model, and the emotional context described below.
3. **Execute** - If the model calls tools, the engine executes them, supplies their results to subsequent reasoning, and re-engages within the configured execution limits.
**Act.** The selected runtime turns reasoning results into channel output. Text and simulation can return materialized effects. Native voice consumes navigation and engagement prompts through its streaming pipeline; the [voice timeline](/channels/voice/audio-pipeline.md#voice-timeline) coordinates fillers, empathy pauses, and tool progress narration within each turn.
The execution paths reuse components without sharing one complete runtime loop:
| Path | How reasoning reaches execution | Boundary to preserve |
| --------------------------------- | --------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------- |
| **Native text and simulation** | Process signals through the shared reasoning entry point and expose supported effects or streamed results | Delivery, persistence, and simulation write behavior remain path-specific |
| **Native voice** | Uses shared navigation and engagement components, then streams speech through its voice pipeline | Consumes navigation and engagement prompts rather than the same completed-effect list |
| **Provider-owned realtime voice** | The selected provider owns the conversation and invokes executor-backed tools | Uses the service-authorized, graph-wide tool set rather than per-turn native graph-state gating |
Response streaming can reduce the wait for complete text before delivery. It does not make these execution paths equivalent. Confirm the service's selected runtime and provider when relying on state-specific behavior.
Filler handling is channel-aware. Voice can play a short acknowledgement while work continues. Asynchronous messaging channels suppress voice-style filler and deliver results through their channel-specific completion flow. See [Email](/channels/email.md#long-running-tools-and-reply-delivery) for a non-live example.
Navigation can also be re-evaluated after a successful tool result rather than waiting for another user message. This occurs only for tool bindings configured for completion-gated navigation; the navigator may remain in the current state or select another valid state. See [Action State Extensions](/agent/context-graphs.md#action-state-extensions).
## Emotional Adaptation
When a voice session has usable emotion data, the engine can add that context through two paths. Simulations may also supply emotion signals for testing, but ordinary text messages do not produce acoustic evidence.
**Per-message annotations.** When acoustic evidence is available, the user message can retain the current detected emotion and valence alongside its transcript. These annotations are model-derived signals, not verified statements about the caller's internal state.
**Session-level steering.** Once the voice runtime has enough evidence, it can add a rolling summary to response prompts:
* **Dominant emotion and trend** - Is the caller improving, stable, or deteriorating?
* **Adaptation instructions** - Targeted guidance based on the caller's emotional quadrant (high-arousal negative callers need de-escalation; low-arousal negative callers need patience)
* **Behavioral signals** - Patterns like repeated interruptions, short response streaks, or extended silences that indicate disengagement or frustration independent of vocal emotion
* **Call-phase urgency** - After extended calls with deteriorating mood, the engine instructs the model to become more direct and resolution-focused
* **Coherence warnings** - When what the caller says and how they sound disagree, the engine flags the ambiguity so the model does not over-commit to a single interpretation
The combination gives the response model recent evidence and adaptation guidance. It does not make emotion classification definitive, and safety or clinical decisions should not rely on emotion inference alone.
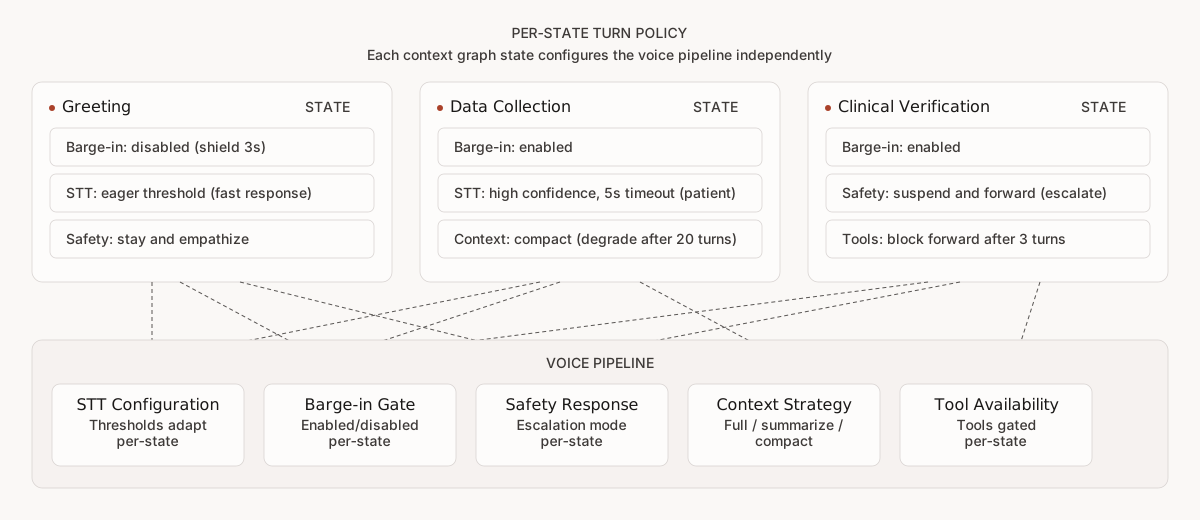
## Per-State Configuration (TurnPolicy)
Each context graph state can configure the pipeline independently. A medication verification state behaves differently than a general scheduling state - not because the reasoning logic changes, but because the state's turn policy tunes the pipeline for that context.
Five areas are configurable per state:
* **Barge-in** - Enable or disable caller interruptions for the active state. The service's minimum speech duration applies during the greeting as well as later responses; there is no separate greeting-shield duration. A quick-answer state can keep barge-in enabled for faster turn-taking.
* **Safety response** - What happens when a safety rule fires. Options: stay in the conversation and respond with empathy, suspend the agent and route to an operator, or log an alert without interrupting.
* **Context strategy** - Choose full history or compact past state groups. A per-state threshold can activate compaction, and the engine can also ratchet to compact mode when prompt usage approaches the configured context limit.
* **Tool controls** - The state defines its actions. Turn policy can additionally block call forwarding entirely or after a configured number of turns.
* **STT sensitivity** (voice only) - End-of-turn thresholds and silence timeouts. Data collection states use higher thresholds and longer timeouts because callers pause between pieces of information. Quick-answer states use lower thresholds for faster responses.
## Model Configuration
The platform supports separate model preferences for navigation and engagement. Navigation selects a path through the context graph; engagement handles tool calling and response generation. Configuring them independently lets teams tune cost, latency, and response quality, but model-backed navigation is not inherently deterministic.
## Graceful Degradation
Selected failure paths have bounded fallbacks so an optional subsystem or a single model timeout does not automatically end a session.
| Component | Failure | Fallback |
| --------------------- | ------------------------------------------------------ | ------------------------------------------------------------------------------ |
| **Emotion detection** | Connection failure or repeated receive errors | Continues without new emotion-derived steering |
| **Navigation model** | Timeout or unavailable configured model | Tries a configured fallback; otherwise remains in the current engageable state |
| **Context pressure** | Estimated prompt usage approaches the configured limit | Compacts past state groups and caps retained history |
These paths reduce failure propagation, but they are not a zero-failure guarantee. Transport loss, exhausted fallbacks, session limits, or failures in required dependencies can still interrupt or end an interaction.
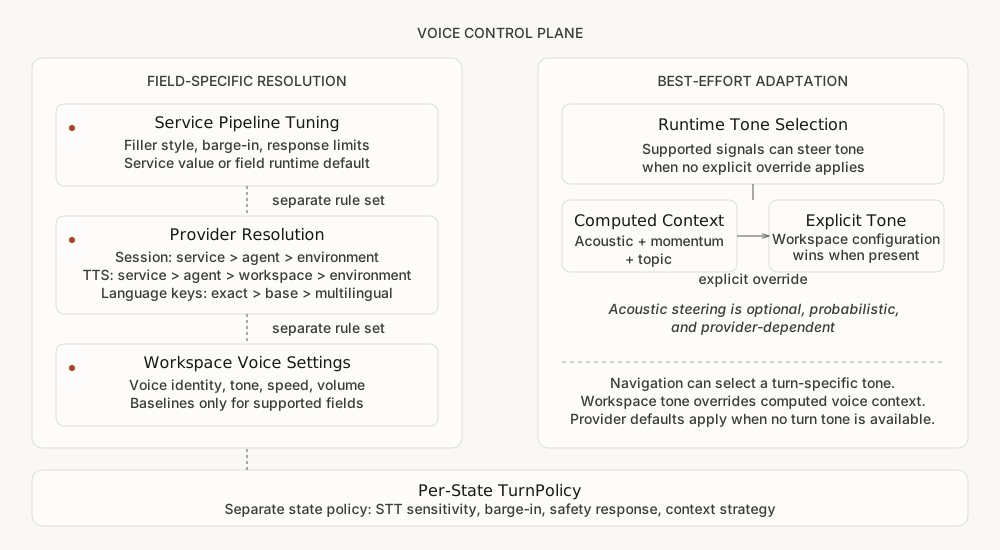
## Voice Control Plane
Voice calls combine service, agent, workspace, and environment settings that control vocal identity and delivery. They do not use one universal override hierarchy. Each field family has its own resolution rule.
| Setting Family | Resolution |
| ---------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Service pipeline tuning** | A service value applies when set; otherwise the field uses its documented runtime default or supported fallback |
| **Session provider** | Service, then agent, then environment |
| **TTS provider** | Service, then agent, then workspace, then environment. Per-language maps check the exact language, base language, and `multilingual` key, with service, agent, and workspace precedence within each key |
| **TTS provider configuration and model** | Workspace provider configuration forms the base, then agent and service configuration override it. A service model is the final model override; unresolved values use the environment configuration. A selected per-language entry can replace the merged base provider configuration |
| **Workspace voice settings** | Provide voice identity, tone, speed, volume, language, domain vocabulary, sensitive topics, and other workspace baselines for the fields that consult them |
| **Per-state `TurnPolicy`** | Controls separate state behavior such as STT sensitivity, barge-in, safety response, and context strategy; it is not another provider-inheritance tier |
When the emotion system has usable evidence, it can derive a turn-level delivery tone and prompt guidance. Navigation can select a turn-specific tone, an explicit workspace tone can take precedence over computed voice context, and provider defaults apply when no turn tone is available. This tone choice is separate from provider and TTS configuration resolution. See [Emotion Detection](/channels/voice/emotion-detection.md) and the [Audio Pipeline](/channels/voice/audio-pipeline.md).
## Concurrency
User input, reasoning, tool execution, and delivery can overlap. A caller can correct a request while a lookup is running, and a tool can finish after the agent has stopped speaking. Receiving information, continuing reasoning, and delivering a response are separate decisions.
Supported runtimes coordinate accepted interaction work while tools and background tasks can run independently. A tool binding separately controls whether work blocks or runs in the background, how success and failure return to the interaction, and how results are retained. Lifecycle support differs by modality; see [Tool Dispatch Configuration](/agent/context-graphs.md#tool-dispatch-configuration).
For example, with a voice lookup configured for background execution and interrupt delivery:
1. The caller asks for Friday's availability and the agent starts the lookup.
2. The voice runtime manages waiting and any configured progress speech while the lookup runs.
3. When the result is ready and continuation is permitted, the agent can present the options without another user message.
4. If the caller changes the request, the new input can interrupt speech and start another reasoning step. The completed lookup and whether to speak about it remain separate; continuation checks account for newer input and pending transcription, but do not establish universal rejection of every stale result.
With several outstanding voice tools, the current continuation path waits for the last completion before considering an automatic response. Earlier results can be recorded without generating separate responses.
Interrupting speech does not undo a tool's completed action. Requesting cancellation is also different from confirming that work stopped. For an external write with an uncertain outcome, check the operation's documented completion status or supported read-back before deciding whether to retry. A transport acknowledgement alone does not establish that the requested change happened.
Voice coordinates fillers, responses, empathy pauses, and progress narration on one timeline. Text uses its supported conversation and background-result lifecycle. These controls do not promise identical delivery timing, recovery of every in-flight task, or bit-exact replay across channels. See [Text Sessions](/channels/text-sessions.md) and the [Voice Timeline](/channels/voice/audio-pipeline.md#voice-timeline).
## Design Direction: Universal Reasoning Harness
The proposed harness extends the shared reasoning contract to work whose input, reasoning, actions, and delivery have independent lifetimes. An external record update could lead to background work and an observed outcome without a conversational reply. The design retains declarative agent and problem definitions while making dependencies, context validity, and ownership of ongoing work explicit.
The broader [universal processing engine design](/agent/universal-reasoning.md#the-broader-universal-processing-engine) separates cut policy, consumer dispatch policy, and effect arbitration policy. This harness develops execution ownership within that architecture. A priority queue, one worker layout, or serial packet processing is an implementation choice rather than a required property of the design.
Current implementations provide the channel behavior described above. Full execution ownership, background behavior selection, and general evidence-preload support are proposed extensions; their presence in this design does not establish support in every runtime or deployment.
### Capture Context, Decide, and Accept Work
| Step | Purpose in the proposed harness |
| ----------- | ------------------------------------------------------------------------------------------------------------- |
| **Cut** | Capture a bounded selection of relevant context while new signals can continue to arrive |
| **Reason** | Interpret that context using the agent and problem definition, through deterministic rules or model reasoning |
| **Enqueue** | Accept intended work with priority, dependencies, and conditions under which it remains valid |
A signal supplies information; the harness decides whether that information requires work. A cut creates a context boundary and need not interrupt current activity. Interruption or invalidation becomes necessary when changed assumptions affect unfinished work. Priority orders work that is eligible to proceed; it cannot satisfy a missing prerequisite or grant permission.
The bounded input captured at a cut is a *processing packet*, called a *quantum* in earlier harness designs. Its scope follows the task rather than a network-packet boundary. Smaller units allow earlier reconsideration but can add overhead and discarded reasoning; larger units preserve more continuity but can leave more work to reconsider after a correction. Forming a packet does not require every consumer to run or produce an output.
One execution owner would accept changes to state and scheduling. Concurrent workers would return proposed guidance, results, or outcomes for that owner to check. The owner would check relevance when accepting a result and again before releasing dependent work, while remaining responsive to control signals during long model requests.
For example, a Friday behavior selection that finishes after the request has changed to Monday must not restore Friday's instructions merely because it completed last. The proposed acceptance checks generalize the narrower voice continuation checks above. Replacement of an execution owner must also prevent the previous owner from continuing to accept changes.
### Background Guidance and Required Evidence
The proposed background selector would compute behavior guidance against captured context while other eligible work continues. Advisory guidance could be adopted at a later reasoning boundary. If an action or response requires a selection, that dependency would hold the affected work until selection succeeds or the defined fallback resolves it. Mandatory constraints remain enforced while selection is pending or fails.
The same distinction applies to [memory and required evidence](/agent/memory.md#context-required-by-a-task). Loading information early can reduce waiting, while required evidence gates the decision that uses it. New contradictions or missing facts can trigger additional authorized retrieval even when they were absent from the initial context declaration.
A model request already in flight has received its context. Accepting new guidance means using it in a later request or cancelling and regenerating unfinished output; changing shared instructions does not rewrite the active request. A correction can require a new decision, while an ordinary update may wait until the next boundary.
Voice filler can acknowledge that work is continuing. Its usefulness depends on measured timing: initial silence, any gap after the filler, and time to meaningful output. Filler does not satisfy a prerequisite or restart the latency measurement.
### Recovery and Human Control
The target contract distinguishes an intended action, its submission attempts, and its confirmed outcome. Recovery would retain pending obligations or explicitly mark them unresolved. An uncertain external submission requires the provider's supported idempotency or reconciliation path before retrying; execution ownership alone cannot guarantee exactly-once effects.
Operator guidance, takeover, and handback need separate authority and scope. The proposed harness would reconsider affected pending work after handback and retain already submitted actions for reconciliation. Current controls and channel limits remain documented in [Operators](/operations-and-safety/operators.md); this design does not promise restoration of every dropped call or recovery of every running tool.
Evaluate recorded-result replay separately from rerunning models. The former inspects execution handling for supplied outcomes; the latter also measures model variability. Agree on covered failures, recovery deadlines, meaningful-output latency, and total cost under a stated workload before assigning production targets. See [Evaluating Concurrence](/platform-overview/evaluating-amigo.md).
## Modality Adapters
Adapters and channel runtimes handle the following input and output responsibilities on the supported native paths. These are behavior categories, not a claim that every channel consumes the same effect objects. Provider-owned realtime voice follows its separate session lifecycle described above.
| Adapter | Signal Production | Output Handling |
| -------------- | ------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------- |
| **Voice** | STT produces utterance signals; enabled prosody analysis supplies emotion signals; silence and barge-in handling follows the voice timeline | Streams responses through TTS; manages fillers, pauses, and termination within the voice lifecycle |
| **Text (SMS)** | Incoming messages produce utterance signals | Respond effects send SMS messages; terminate effects end the session |
| **Simulation** | Test parameters inject utterance and emotion signals | Effects are captured as simulation evidence; tool writes use simulation source tagging rather than a separate database branch |
New modalities can reuse the signal-and-effect contract through an adapter. Channel-specific delivery, lifecycle, authorization, and failure handling still require integration and testing.
{% hint style="info" %}
**Related sections** - See [Context Graphs](/agent/context-graphs.md) for how the engine navigates problem spaces, [Functional Memory](/agent/memory.md) for bounded cross-session context, and [Voice Agent](/channels/voice.md) for voice-specific pipeline details. [Dynamic Behaviors](/agent/context-graphs/dynamic-behaviors.md) documents a separate Classic API capability.
{% endhint %}
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.concurrence.com/agent/reasoning-engine.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.