> For the complete documentation index, see [llms.txt](https://docs.concurrence.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.concurrence.com/operations-and-safety/runtime-safety.md).

# Runtime Safety

Current runtime safety controls, their enforcement boundaries, operator intervention, and evidence-based release practices.

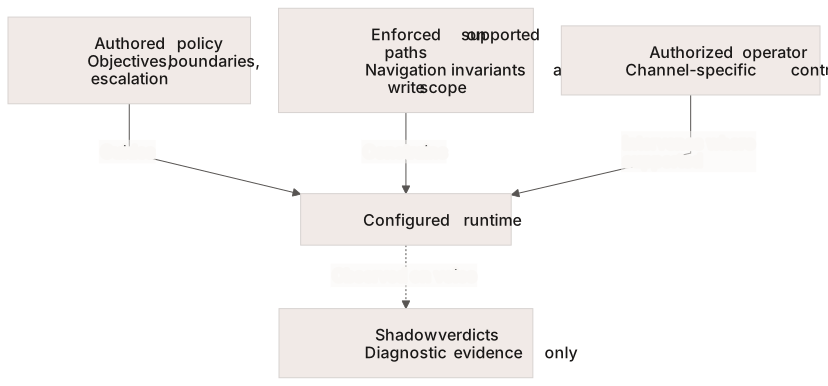
Runtime safety is a layered system. Authored conversation policy guides the agent, structural controls constrain supported execution paths, server-side authorization limits writes, and operators can intervene through the unified Runs surface.

The current architecture does not depend on a separate semantic monitoring or regulatory-triage service. Safety-critical behavior must be expressed in the agent's context graph, tool permissions, escalation instructions, and operating procedures, then verified against representative scenarios.

<figure><img src="https://3635224444-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvcLyiHRcwv7g83p6vxAd%2Fuploads%2Fgit-blob-0e497d539a7be69fffb465d7d87d0fc06be05bf7%2Fruntime-control-boundaries.svg?alt=media" alt="Authored policy guides reasoning. Supported execution paths enforce structural and authorization controls. Voice shadow observers provide diagnostic evidence without changing the live call. Authorized operators use channel-specific intervention controls."><figcaption><p>These are distinct responsibilities, not a universal sequence of safety gates. The control map specifies each runtime’s scope.</p></figcaption></figure>

## Control Map

| Control                                 | Scope                                            | Current Behavior                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                         |
| --------------------------------------- | ------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| **Context graph policy**                | Voice and text                                   | States define objectives, available tools, exit conditions, guardrails, and boundary constraints that shape agent behavior.                                                                                                                                                                                                                                                                                                                                                                                                                                              |
| **Graph navigation invariants**         | Platform-managed context graph runtime           | Navigation resolves to an engageable state, detects loops, and caps per-turn transitions in code.                                                                                                                                                                                                                                                                                                                                                                                                                                                                        |
| **Cross-runtime invariant observation** | Voice                                            | The platform records shadow verdicts for engageable-state, loop, and iteration checks. These verdicts do not change the live call.                                                                                                                                                                                                                                                                                                                                                                                                                                       |
| **Response guardrail observation**      | Voice                                            | Candidate responses are compared with the active state's guardrails and boundary constraints in shadow mode. Verdicts are diagnostic only.                                                                                                                                                                                                                                                                                                                                                                                                                               |
| **Integration approval policy**         | Text conversations                               | A top-level integration tool call can pause for an authorized approve or reject decision when its integration policy gates the operation.                                                                                                                                                                                                                                                                                                                                                                                                                                |
| **Write scope**                         | Supported agent write tools                      | A server-side write scope binds model-originated writes to an allowed workspace and entity; each registered tool constrains its resource shape and source-appropriate confidence.                                                                                                                                                                                                                                                                                                                                                                                        |
| **In-flight write deduplication**       | Supported voice runtimes                         | An identical write-tool call is short-circuited while the first invocation is still running. A later invocation can proceed after the first finishes.                                                                                                                                                                                                                                                                                                                                                                                                                    |
| **Caller verification**                 | Voice and text                                   | A caller matched by phone number or a supplied `entity_id` stays unverified, and the patient record stays out of the agent's context, until the stated full name and date of birth match exactly one record through `world_confirm_patient_identity`. Until then, built-in patient-record reads return `verification_required`; afterwards they return only the caller's own record or a household member's whose record names them as guardian or under a power of attorney. Reads through integration endpoints are not gated by this check.                           |
| **Call-opening notice**                 | Platform-managed voice and `gpt_realtime`        | Every call opens with an authored AI and recording notice in English or Spanish that configuration cannot change. If it cannot be rendered, the call continues without it.                                                                                                                                                                                                                                                                                                                                                                                               |
| **Transfer destinations**               | Voice                                            | A dynamic transfer dials only a number listed in the service's `approved_destinations`; any other number is refused without dialing.                                                                                                                                                                                                                                                                                                                                                                                                                                     |
| **Crisis resource guidance**            | Text, platform-managed voice, and `gpt_realtime` | The agent's instructions always carry the deployment region's crisis resource and tell it to give that resource on suicidal thoughts, self-harm, or an overdose. On `gpt_realtime` the rule also covers hints and tells the agent to give the resource in its first reply to any sign, after at most one short sentence of care, so the caller hears it before talking over the agent or hanging up. This is model guidance, not a deterministic check. Hints are read broadly, so a caller with an ordinary reason, such as moving away, can also hear the crisis line. |
| **Self-harm script on text**            | Text                                             | A message that matches the self-harm patterns is answered with a reviewed script naming the region's crisis line, where one exists, and the emergency number. Pattern matching can miss a phrasing; the crisis guidance above still applies.                                                                                                                                                                                                                                                                                                                             |
| **Spoken-reply check**                  | Platform-managed voice                           | Before the caller hears a reply, a pattern check and then a model check review it for record details shared with an unverified caller, dosing or medication-change advice, a diagnosis, a promise to contact emergency services, and a booking, cancellation, or move claim with no successful write of that kind on the call. A message claimed as taken needs a written ticket. A blocked reply is replaced by a short correction in English or Spanish, or by the emergency script after an emergency on the call. Either check can miss or over-match.               |
| **Text reply check**                    | Text                                             | Before a text reply is sent on any channel, a pattern check reviews it for dosing or medication-change advice, a promise to contact emergency services, and a booking, cancellation, or message claim with no successful write of that kind in the same turn. A failed tool call, including an integration's 4xx or 5xx, backs nothing. A blocked reply is replaced by a short correction in English or Spanish, or by the emergency script when the message described an emergency. There is no model check on text, and the pattern check can miss or over-match.      |
| **Speech recognition failure**          | Platform-managed voice                           | A failed recognizer is replaced once by another that supports the caller's language. Otherwise the agent apologizes and transfers to the fixed forwarding destination, or ends the call.                                                                                                                                                                                                                                                                                                                                                                                 |
| **Request for a person**                | Text, platform-managed voice, and `gpt_realtime` | A request to speak with a person does not end the conversation. The agent is told to transfer when `forward_call` is available, to offer a message only when its state can record one as a ticket, and otherwise to say it can't connect the caller and tell them how to reach the team without making up a number.                                                                                                                                                                                                                                                      |
| **Operator control**                    | Eligible live runs                               | Authorized operators can listen, take over, send guidance, author a text turn, and hand control back, depending on channel.                                                                                                                                                                                                                                                                                                                                                                                                                                              |

This map distinguishes controls that actively enforce behavior from controls that only produce evidence. That distinction matters when setting clinical and operational expectations.

## Safety in the Agent Policy

The agent evaluates the conversation within its normal reasoning loop. The platform-level checks in the control map cover a few narrow cases, but they do not compensate for missing escalation instructions or incomplete boundaries.

For each safety-sensitive state, define:

* **Objective** - What the agent is trying to accomplish in that state.
* **Allowed tools** - The smallest tool set needed for the task.
* **Boundary constraints** - What the agent must not claim, recommend, or attempt.
* **Escalation conditions** - Observable situations that require a human or a configured transfer target.
* **Safe fallback** - What the agent should say and do if the required person, tool, or destination is unavailable.
* **Exit conditions** - The evidence needed before the graph advances.

On the Platform API, reusable policy that spans states should be expressed through shared context graph structure, state guidance, transitions, eligible tools, and tested authoring conventions. Classic dynamic behavior sets are a separate Classic API capability and are not a Platform runtime control.

{% hint style="warning" %}
Safety instructions are model-facing policy. They are not a substitute for server-side authorization, clinical governance, or a staffed escalation process.
{% endhint %}

## Structural Navigation Controls

The platform-managed context graph navigator enforces three structural properties during a turn:

1. **Engageable landing** - Routing states are resolved until the conversation reaches a state that can handle the next user interaction.
2. **Loop handling** - Repeated navigation is detected so the engine does not traverse the graph indefinitely.
3. **Transition cap** - A bounded number of state changes can occur within one turn.

If navigation cannot resolve safely, this runtime stays on the last engageable state rather than presenting a routing-only state to the caller.

The voice layer also observes these properties across supported runtimes. That observer is shadow-only: it records diagnostic verdicts but does not interrupt, reroute, or end a call. Runtimes that navigate independently therefore do not inherit the platform-managed navigator's enforcement merely because they produce the same telemetry.

## Guardrail Evaluation Status

State guardrails and boundary constraints are included in the agent's active instructions. Separately, the platform runs a lightweight response-text evaluator on voice calls and records whether a candidate response appears to overlap a configured rule.

{% hint style="warning" %}
The response evaluator is shadow-only. A recorded `block` verdict does not block or rewrite the response, and evaluator failure does not affect the call. Treat these verdicts as calibration and regression evidence, not as an enforced clinical safety boundary.
{% endhint %}

Because shadow evaluation observes text rather than clinical truth, teams should review false positives and false negatives before using its output in an operational process.

## Write Safety

### Integration Tool Approval

Workspace integrations can set an approval policy of `none`, `writes`, or `all`. On supported text conversation paths, a gated top-level integration call is parked before execution until an authorized reviewer approves or rejects it. The default is `none`.

This mechanism is conversation-scoped and fail-closed. It does not currently gate integration tools called from companion skills, and it does not apply to voice execution. It is also separate from external write proposals: integration approval pauses a conversation tool call, while an external proposal stages a connector payload for later review and delivery.

### Agent Write Scope

Supported agent write tools receive a server-constructed write scope that restricts which workspace and entity the operation can target. The registered tool contract separately constrains the resource shape and assigns or caps the confidence available to model-originated data.

These checks protect the persistence boundary even if the model supplies an unexpected identifier. System-originated connector and projection work follows separate trusted-service authorization and is not evidence that an agent can bypass its own scope.

### Duplicate Calls

Supported voice runtimes track identical write-tool calls that are already in progress. If the model repeats the same write before the first completes, the duplicate is rejected as already running. This prevents concurrent duplicates; it is not a permanent idempotency guarantee for later calls.

Operations that need durable idempotency should still use the operation's documented idempotency key or destination-specific protection.

### External Delivery

Recording an observation in the world model does not confirm an external mutation. Unattended connector delivery and the review-gated external write proposal flow were retired with the connector runner on October 10, 2026, so world-model observations are not delivered to external systems by a connector. An external mutation happens through a tool the agent calls, such as an integration endpoint, and its result is the evidence of what the destination accepted.

## Human Intervention

The unified Runs surface gives operators one place to monitor eligible live work:

* **Voice** - Join in listen mode, explicitly take over, send guidance, switch mode, and hand the call back.
* **Text channels** - Pause an eligible run, author the next turn, and hand control back.
* **History** - Inspect the transcript, run metadata, available analysis, and recorded operator actions.

Operator actions require the Operator update permission, available to operator, admin, and owner roles. Supported action routes bind the requested operator identity to the authenticated caller and emit operator-attributed events for takeover-related actions.

An authored escalation policy must also define what happens when no operator is available. Appropriate fallbacks can include a configured transfer target, callback workflow, emergency instruction, or a bounded refusal. Do not assume the platform automatically pages a clinician or creates a post-call review item.

## Validation Before Release

Simulations exercise the current workspace configuration through the real reasoning and tool path. Simulation-originated world-model writes are tagged so production EHR delivery and production analytics can exclude them, but simulations do not create an isolated configuration branch and do not replace every external dependency with a stub.

Use dedicated test workspaces, test entities, or safe integration environments when a scenario could reach a real external system. Separate broad text-tier validation from real-audio tests that measure transcription, speech rendering, turn timing, and media attachment.

A practical release review includes:

1. Run targeted cases for each safety boundary and escalation path.
2. Run regression suites against the configuration intended for release.
3. Inspect normalized checks, transcripts, tool calls, and failure reasons.
4. Review shadow guardrail and control-invariant evidence where available.
5. Confirm operator staffing and fallback procedures.
6. Deliberately update the pinned `release` version set when the evidence is acceptable.

Simulation results and drift analysis do not automatically block version-set promotion or roll back a release. Promotion and rollback are deliberate operator actions.

## Production Review

After release, use conversation evaluations, run history, connector outcomes, and operational metrics to find changes in behavior. Compare defined cohorts and stable time windows rather than treating a single aggregate score as proof of safety.

When a regression appears:

1. Identify affected channels, services, versions, and cohorts.
2. Add or update a reproducible simulation case.
3. Verify whether the issue is agent behavior, tool behavior, media quality, or destination failure.
4. Correct the smallest responsible configuration or integration boundary.
5. Re-run the affected suite before moving the release pin.

## What Runtime Safety Does Not Guarantee

* **Perfect outcomes** - Model behavior and external systems remain fallible.
* **Automatic clinical triage** - The crisis resource guidance and the voice and text reply checks cover narrow cases. Organizations must author, test, and staff their own clinical escalation protocols.
* **Enforced shadow verdicts** - Guardrail and cross-runtime invariant observers currently record evidence only.
* **Universal human review** - Only supported top-level text integration calls use an approval path. The external write proposal flow was retired with the connector runner.
* **Automatic deployment rollback** - Teams decide when to move a version-set pin.
* **Automatic outbound reconciliation** - Unattended connector delivery is retired; verify each integration call's result at the destination.

{% hint style="info" %}
Triage and safety evaluation support operational decisions; they do not replace clinical assessment. Organizations remain responsible for clinical protocols, escalation staffing, destination verification, and regulatory review.
{% endhint %}

## Related Documentation

* [Context Graphs](/agent/context-graphs.md)
* [Operators](/operations-and-safety/operators.md)
* [Testing and Evaluation](/testing/testing.md)
* [Connectors and EHR](/data/connectors-and-ehr.md)
* [Compliance](/operations-and-safety/compliance.md)
* [Safety and monitoring APIs](https://docs.concurrence.com/developer-guide/platform-api/safety)


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://docs.concurrence.com/operations-and-safety/runtime-safety.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.
