> For the complete documentation index, see [llms.txt](https://docs.concurrence.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.concurrence.com/platform-overview/deployment-model.md).
# Deployment Model
Define deployment scope, validate a candidate, select reviewed configuration, and manage release changes across isolated workspaces.
A release selects the configuration that subsequent interactions will resolve. Teams establish a baseline, test a candidate, approve it, and inspect the resulting production evidence. These are deliberate team decisions supported by platform capabilities.
The [Operating Model](/platform-overview/operating-model.md) assigns responsibility for those decisions. This page covers the release process, version selection, and workspace separation. [Core Concepts](/platform-overview/core-concepts.md) introduces the configuration relationships.
## Define the Deployment Boundary
Start with a specific operational outcome and the systems needed to achieve it. For appointment outreach, that includes the source of eligibility, current scheduling data, recipient consent, a provisioned channel, confirmed write-back, and a staffed exception path.
Agree on the responsibilities before authoring the agent:
* **Data access** - Which records are available, how fresh they must be, and which system remains authoritative for each external action.
* **Workflow ownership** - Who authors clinical and operational policy, handles exceptions, and approves changes.
* **Channel operations** - Who supplies consent evidence and approved content, and which provisioning Concurrence manages.
* **Measurement** - How the team distinguishes an attempted action from a confirmed outcome and compares results with the baseline.
* **Integration** - Which supported APIs, connectors, and data-access paths connect the deployment to existing applications and reporting.
The Developer Console is one interface to these capabilities. Customer applications can use supported APIs and provisioned data access for their own workflows and reporting. A hosted workspace, a customer-owned source system, and a separately agreed deployment arrangement have different data boundaries; confirm the actual arrangement rather than assuming that integration alone moves all processing into the customer's infrastructure.
## Phased Rollout
### Phase 1: Match
Establish the baseline for a defined workflow. Select the eligible cases, escalation paths, evidence, and outcome measures, then compare agent-assisted and existing operations on the same basis.
During this phase:
* Context Graphs encode the approved workflow and operating boundaries.
* Metrics compare eligible agent evidence with the chosen baseline, using the same definitions and filters.
* Operators cover the authored escalation paths and unavailable-agent fallback.
* Retained runs, traces, evaluations, and review evidence inform the next phase when those artifacts are available.
### Phase 2: Discover
With a baseline established, teams analyze observed evidence to form hypotheses about which changes may improve outcomes. Correlation in metrics or traces is not proof that a configuration variable caused the result.
Questions to investigate include:
* Where cases fail or require manual follow-up
* Which missing information delays completion
* Whether escalation reaches the right team with enough context
* Which candidate changes improve outcomes on comparable cases
### Phase 3: Prove
Candidate changes should be exercised through representative simulations, targeted integration tests, and isolated operational validation before production. Teams define the required case count, comparison method, risk checks, and release criteria for the use case.
The prove phase uses:
* Candidate and control version sets with explicit configuration snapshots.
* Simulation suites that exercise common paths, edge cases, and regressions.
* Metric comparisons that preserve filters, sample sizes, missing evidence, and uncertainty.
* Human review for safety-sensitive or clinically consequential behavior.
Simulation evidence supports a release decision; it does not certify safety or reproduce production deterministically.
### Phase 4: Scale
After an authorized reviewer approves a candidate, teams can copy its version-set configuration to `release`. Continue monitoring production evidence and keep a tested rollback configuration; promotion does not prove that future behavior will remain unchanged.
## What a Reviewable Release Includes
Keep the following evidence with the release decision:
* The workflow and intended outcome, including the change from the baseline.
* The selected agent and Context Graph versions, service settings, and related tool or integration changes.
* Relevant simulation, audio, and integration results, with missing evidence and known limitations visible.
* The approving owner, rollout scope, observation plan, and recovery procedure.
A version set captures part of this record. It does not freeze source data, generated memory, every integration setting, or the external systems the workflow depends on. Restoring a previous configuration also does not undo an external mutation that already succeeded.
## Version Sets
Version sets are named service configurations that select agent and Context Graph versions, model preferences, and a supported non-voice turn runtime. They provide reviewable snapshots for testing and release management.
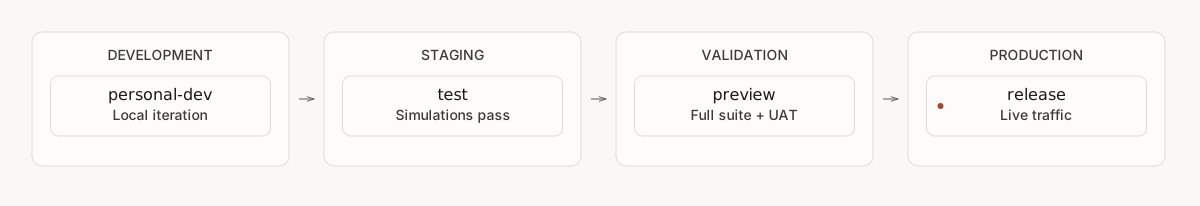
Every Platform service must contain a `release` version set. When service creation omits version sets, the API creates an unpinned `release` set. Other names such as `personal-dev`, `test`, or `preview` are customer conventions, not additional automatic environments.
### Promotion Flow
A recommended path from development to production:
1. **Personal candidate** - Create a named version set, pin the intended agent and Context Graph versions, and inspect the resolved configuration.
2. **Targeted test** - Run the suites and integration checks relevant to the change.
3. **Shared candidate** - Optionally copy the configuration to a team-named set such as `preview` for broader review.
4. **Release** - After approval, copy the reviewed candidate configuration to `release` and verify the stored result.
A version set can pin exact agent and Context Graph versions and carry model preferences. A pinned component changes only when its stored version number changes. An unpinned component resolves to the latest available version when configuration is loaded, so publishing a new version can affect later sessions without a separate pin update. Pin `release` when production behavior should change only through a reviewed configuration update.
## Applying Version-Set Changes
The Platform API upserts individual named version sets on a service. Agent Forge can compare sets, copy a source set to a target, and back up the previous `release` configuration during its promote workflow unless that backup is explicitly disabled.
Treat a version-set update as a change to subsequent configuration resolution, not as an in-place migration of every active interaction. A live session or durable conversation actor can retain configuration loaded earlier. Validate the new `release` value, monitor new runs, and keep a rollback path rather than assuming every next message immediately uses the update.
Use retained configuration versions, Forge diffs, simulation evidence, and applicable audit records together when reviewing a release. No single artifact proves that the candidate produced the intended runtime outcome.
## Multi-Workspace Tenancy
Workspaces are the isolation boundary for data, configuration, and access control. When you need separation between regions, cohorts, or business lines, you create separate workspaces.
Common reasons to use multiple workspaces
* **Data residency**: Use separately provisioned regional deployments and verify their full data flows
* **Cohort isolation**: Separate patient populations (e.g., different clinical programs)
* **Blast radius**: Limit the impact of configuration changes to a single workspace
* **Governance**: Independent roles, audit trails, and promotion controls per workspace
A typical setup for a multi-region deployment:
| Workspace | Region | Purpose |
| ---------------------------- | ---------- | ------------------------------- |
| `acme-cardio-useast` | US East | Cardiology program, US patients |
| `acme-cardio-eucentral` | EU Central | Cardiology program, EU patients |
| `acme-cardio-useast-staging` | US East | Staging environment for US |
Each workspace has its own services, tools, version sets, and access controls. Changes roll out per workspace, so you can deploy to staging, validate, and promote to production without affecting other workspaces.
## Service Channel and Environment
A service's primary channel behavior, supported runtime environment, and organizational tags have different purposes. Treat them as part of the reviewed configuration. Tags help teams organize resources; they do not establish tool permissions, model availability, or a release gate.
Workspace separation and service configuration also serve different purposes. Use the [Workspaces](/data/workspaces.md) guide for isolation and the [Services Developer Guide](https://docs.concurrence.com/developer-guide/platform-api/workspaces/services) for the current configuration contract.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation dynamically by asking a question.
Perform an HTTP GET request on the current page URL with the `ask` query parameter, and the optional `goal` query parameter:
```
GET https://docs.concurrence.com/platform-overview/deployment-model.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is optional and describes the broader end goal you are ultimately trying to accomplish on behalf of the user. GitBook uses it to tailor the answer towards what is most useful for that goal.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.